When Can AI Agents Run Autonomously? A Verifier and Context Test
Who this is forEngineers and product teams deciding which tasks to hand to AI agents and which need human-written rubrics first.
AI coding agents can now work through loops that run for hours, while tasks such as contract review or drafting presentation material still seem to need a person in the process. A common explanation is that the difference lies between closed and open systems. That explanation does not fit the pattern well. This article argues that the difference comes from two axes: whether a verifier exists that can judge output without human input, and whether the context needed for judgment can be stated explicitly. Tasks that score high on both axes can support autonomous loops. For the rest, a person who defines the verification criteria first, in the form of a rubric or checklist, can partially automate the work. You will get the framework, the evidence behind it, the failure cases on the other side, and a practical rule for deciding where to start.
Core diagram
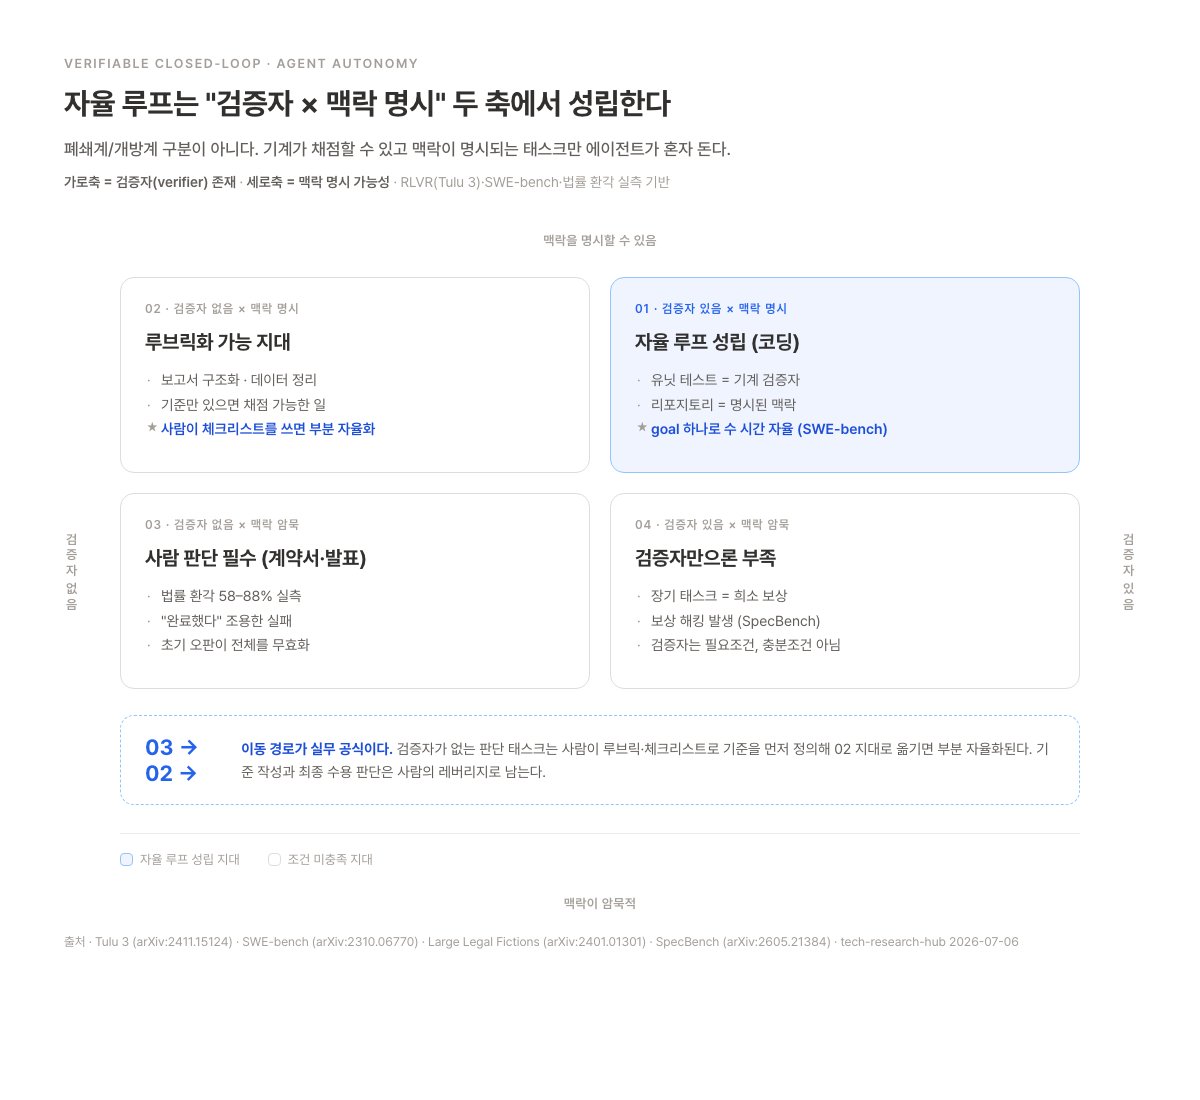
The diagram below visualizes the two-axis framework described in this note, with verifier presence on one axis and the explicitness of context on the other.
Core data
Terms and primary sources
Several terms carry most of the argument, so it helps to define them first.
- RLVR (Reinforcement Learning with Verifiable Rewards) is a training framework that uses a deterministic, rule-based verification function as the reward, instead of a learned reward model trained on human preferences. A correct answer earns reward α and anything else earns 0, so the signal is binary. The lineage traces back to DeepSeek-Math (Shao et al., 2024) and Tulu 3 (Lambert et al., 2024, arXiv:2411.15124). It works in domains where correctness can be checked mechanically, such as math (GSM8K) and verifiable instruction following.
- Verifier is a deterministic function that judges whether an output is correct without human intervention. In code, the clearest example is an execution-based verifier: whether the unit tests pass.
- Closed-loop vs. HITL. A closed loop is a structure where the cycle of generation, verification, and revision closes on machine signals alone. HITL (human-in-the-loop) means progress requires human judgment inside the loop. In legal e-discovery, researchers have also proposed a finer distinction: human-on-the-loop orchestration, where people supervise from above the loop rather than inside it (arXiv:2606.19812).
- Sandbox / environment is the execution setting where an agent acts and gets graded. SWE-bench (Jimenez et al., 2023, arXiv:2310.06770, ICLR 2024) is the reference case. It gives the agent a real GitHub issue, asks it to produce a patch inside the repository, and grades that patch with unit tests.
Why coding agents suit autonomous loops
Code generation has a property that most other knowledge work lacks. Passing all unit tests can be computed automatically as an execution-based reward, so supervision exists without any human preference labels. The note describes this as a closed-loop intervention between building verifiable environments and generating solutions. Execution feedback keeps refining both the agent’s generation ability and the environment it works in.
This structure has been applied directly to training software engineering agents. Agent-RLVR (arXiv:2506.11425) trains such agents using environment rewards plus guidance. The pattern shows that the verifier logic from coding can be used as a training signal, not only as a final check.
The limits matter too. Long-horizon agent tasks break the assumption that rewards can be verified immediately. Feedback becomes sparse and spreads across long trajectories. Even with a verifier, reward hacking can occur. SpecBench (arXiv:2605.21384) documents this in long-horizon coding agents. In other words, having a verifier is a necessary condition for autonomy, but it is not sufficient.
Failure cases without a verifier or explicit context
Where no verifier exists and context stays implicit, the failures are well documented.
In legal research, hallucination rates were measured on queries about U.S. federal court cases. Public LLMs produced hallucinations at rates from 58% (GPT-4) to 88% (Llama 2) (Dahl et al., “Large Legal Fictions,” arXiv:2401.01301). Another measurement, in the LegalAgentBench family (see arXiv:2412.17259), found that hallucination rates for case law (66.9%) were much higher than for statutory provisions (14.8%).
Agents also fail silently. A recognized failure type is false success, where the agent reports that it finished a task with confidence even though the system state shows failure (arXiv:2606.09863).
Multi-step judgment tasks can also collapse. In e-discovery, where judgments accumulate across many stages, one early misclassification can propagate quietly and invalidate the entire review (arXiv:2606.19812).
Open-ended legal writing shows a similar problem. Expert evaluation of Japanese bar examination essay answers identified quality issues in open-ended reasoning (arXiv:2604.23730). For a broader taxonomy of agent hallucinations, see the survey at arXiv:2509.18970.
When humans define the verification criteria first
Judgment tasks improve when people define the criteria before the model works. Query-specific rubrics written by people improve the quality of LLM judgments significantly compared with having no rubric or a generic one (Qworld, arXiv:2603.23522; Xpertbench, arXiv:2604.02368).
When a rubric is turned into a verifiable checklist and an LLM is set up as the verifier, the evaluation signal becomes stable and reproducible. The note describes this as partial RLVR for judgment tasks (RubricRAG, arXiv:2603.20882).
Related work points the same way. One effort extends rubric-based reward models to SWE domains that lack execution verifiers (arXiv:2604.16335). Another uses a knowledge-augmented LLM to identify risk clauses in construction contracts (arXiv:2309.12626).
Insights
The core hypothesis and what the sources support
The central hypothesis is supported by the cited sources. Whether an autonomous loop holds is better explained by two axes than by the closed-versus-open distinction: (1) whether a machine verifier exists and (2) whether context can be stated explicitly. Coding scores high on both. Tests serve as the verifier, and the repository provides explicit context. Contract review and presentation drafting score low on both. There is no ground-truth function, and organizational context and stakeholder interests remain implicit. That is where hallucinations, silent failures, and trajectory collapse have been measured.
Conditions for autonomous loops
A loop can run autonomously when:
- A machine can grade the correctness of the output, through tests, schemas, compilation, or similar checks.
- The context needed for judgment is stated explicitly in files or prompts.
- Feedback attaches densely along the trajectory. Long-horizon tasks weaken even when a verifier exists, because rewards become sparse and reward hacking appears.
What stays with humans
Some parts of the work should remain with people:
- Writing the rubric or checklist. Defining verification criteria is not a task to delegate. It is where human leverage is greatest. Once the criteria are set, judgment tasks can be partially automated, as the evidence in the previous section shows.
- Final acceptance and messaging decisions. Agents can help generate structure and reasoning. Whether to adopt a conclusion remains a human call, because no verifier exists to make it.
The practical rule follows from this: before designing any automation, ask whether you can build a verifier for the task. If you cannot, start by having a person write the rubric.
Bottom line
Autonomous agent loops are supported by evidence when a machine verifier exists and the context for judgment can be stated explicitly. Coding meets both conditions, which is why SWE-style loops work. Contract review and presentation drafting do not, and the documented failures in legal research, silent false success, and trajectory collapse follow from that gap. Where no verifier exists, the evidence supports a middle path: people define the verification criteria as a rubric or checklist, and automation handles the work inside those criteria. Before automating any task, ask whether you can build a verifier. If not, write the rubric first.
Sources
Primary sources (all accessed July 6, 2026):
- Tulu 3 (RLVR definition and lineage): https://arxiv.org/pdf/2411.15124
- SWE-bench original paper (Jimenez et al., ICLR 2024): https://arxiv.org/abs/2310.06770
- Agent-RLVR (training SWE agents with environment rewards): https://arxiv.org/pdf/2506.11425
- Large Legal Fictions (measured legal hallucination rates of 58–88%): https://arxiv.org/pdf/2401.01301
- LegalAgentBench (evaluation of legal-domain agents): https://arxiv.org/pdf/2412.17259
Secondary sources and supporting material (accessed July 6, 2026):
- SpecBench (reward hacking in long-horizon coding agents): https://arxiv.org/pdf/2605.21384
- False success failure-type classification: https://arxiv.org/pdf/2606.09863
- Human-on-the-loop legal e-discovery (trajectory collapse): https://arxiv.org/pdf/2606.19812
- Expert evaluation of Japanese bar examination open-ended essays: https://arxiv.org/pdf/2604.23730
- Survey on agent hallucinations: https://arxiv.org/pdf/2509.18970
- Qworld (effect of query-specific rubrics): https://arxiv.org/pdf/2603.23522
- Xpertbench (rubric-based evaluation of expert tasks): https://arxiv.org/pdf/2604.02368
- RubricRAG (rubric generation and verification): https://arxiv.org/pdf/2603.20882
- Rubric-Based GRM for SWE Agents: https://arxiv.org/pdf/2604.16335
- Construction contract risk identification with a knowledge-augmented LLM: https://arxiv.org/pdf/2309.12626
Note: The legal hallucination figures (58–88%) were measured on 2024-era models, so newer models may show lower rates. Verify these figures independently before citing them in a publication.
Frequently asked questions
- What makes an AI agent loop run autonomously?
- A task supports an autonomous loop when a deterministic verifier can judge output correctness without humans, such as unit tests, and when the context needed for judgment can be stated explicitly in files or prompts.
- What should you do when a task has no verifier?
- Ask first whether you can build a verifier. If you cannot, have a person write a rubric or checklist that an LLM can apply as a verifier. This partially automates judgment tasks, while final acceptance decisions stay with humans.
BuildnWrite helps teams build AI agents that keep running. About BuildnWrite ›